Sparring
An AI judge with 21 criteria
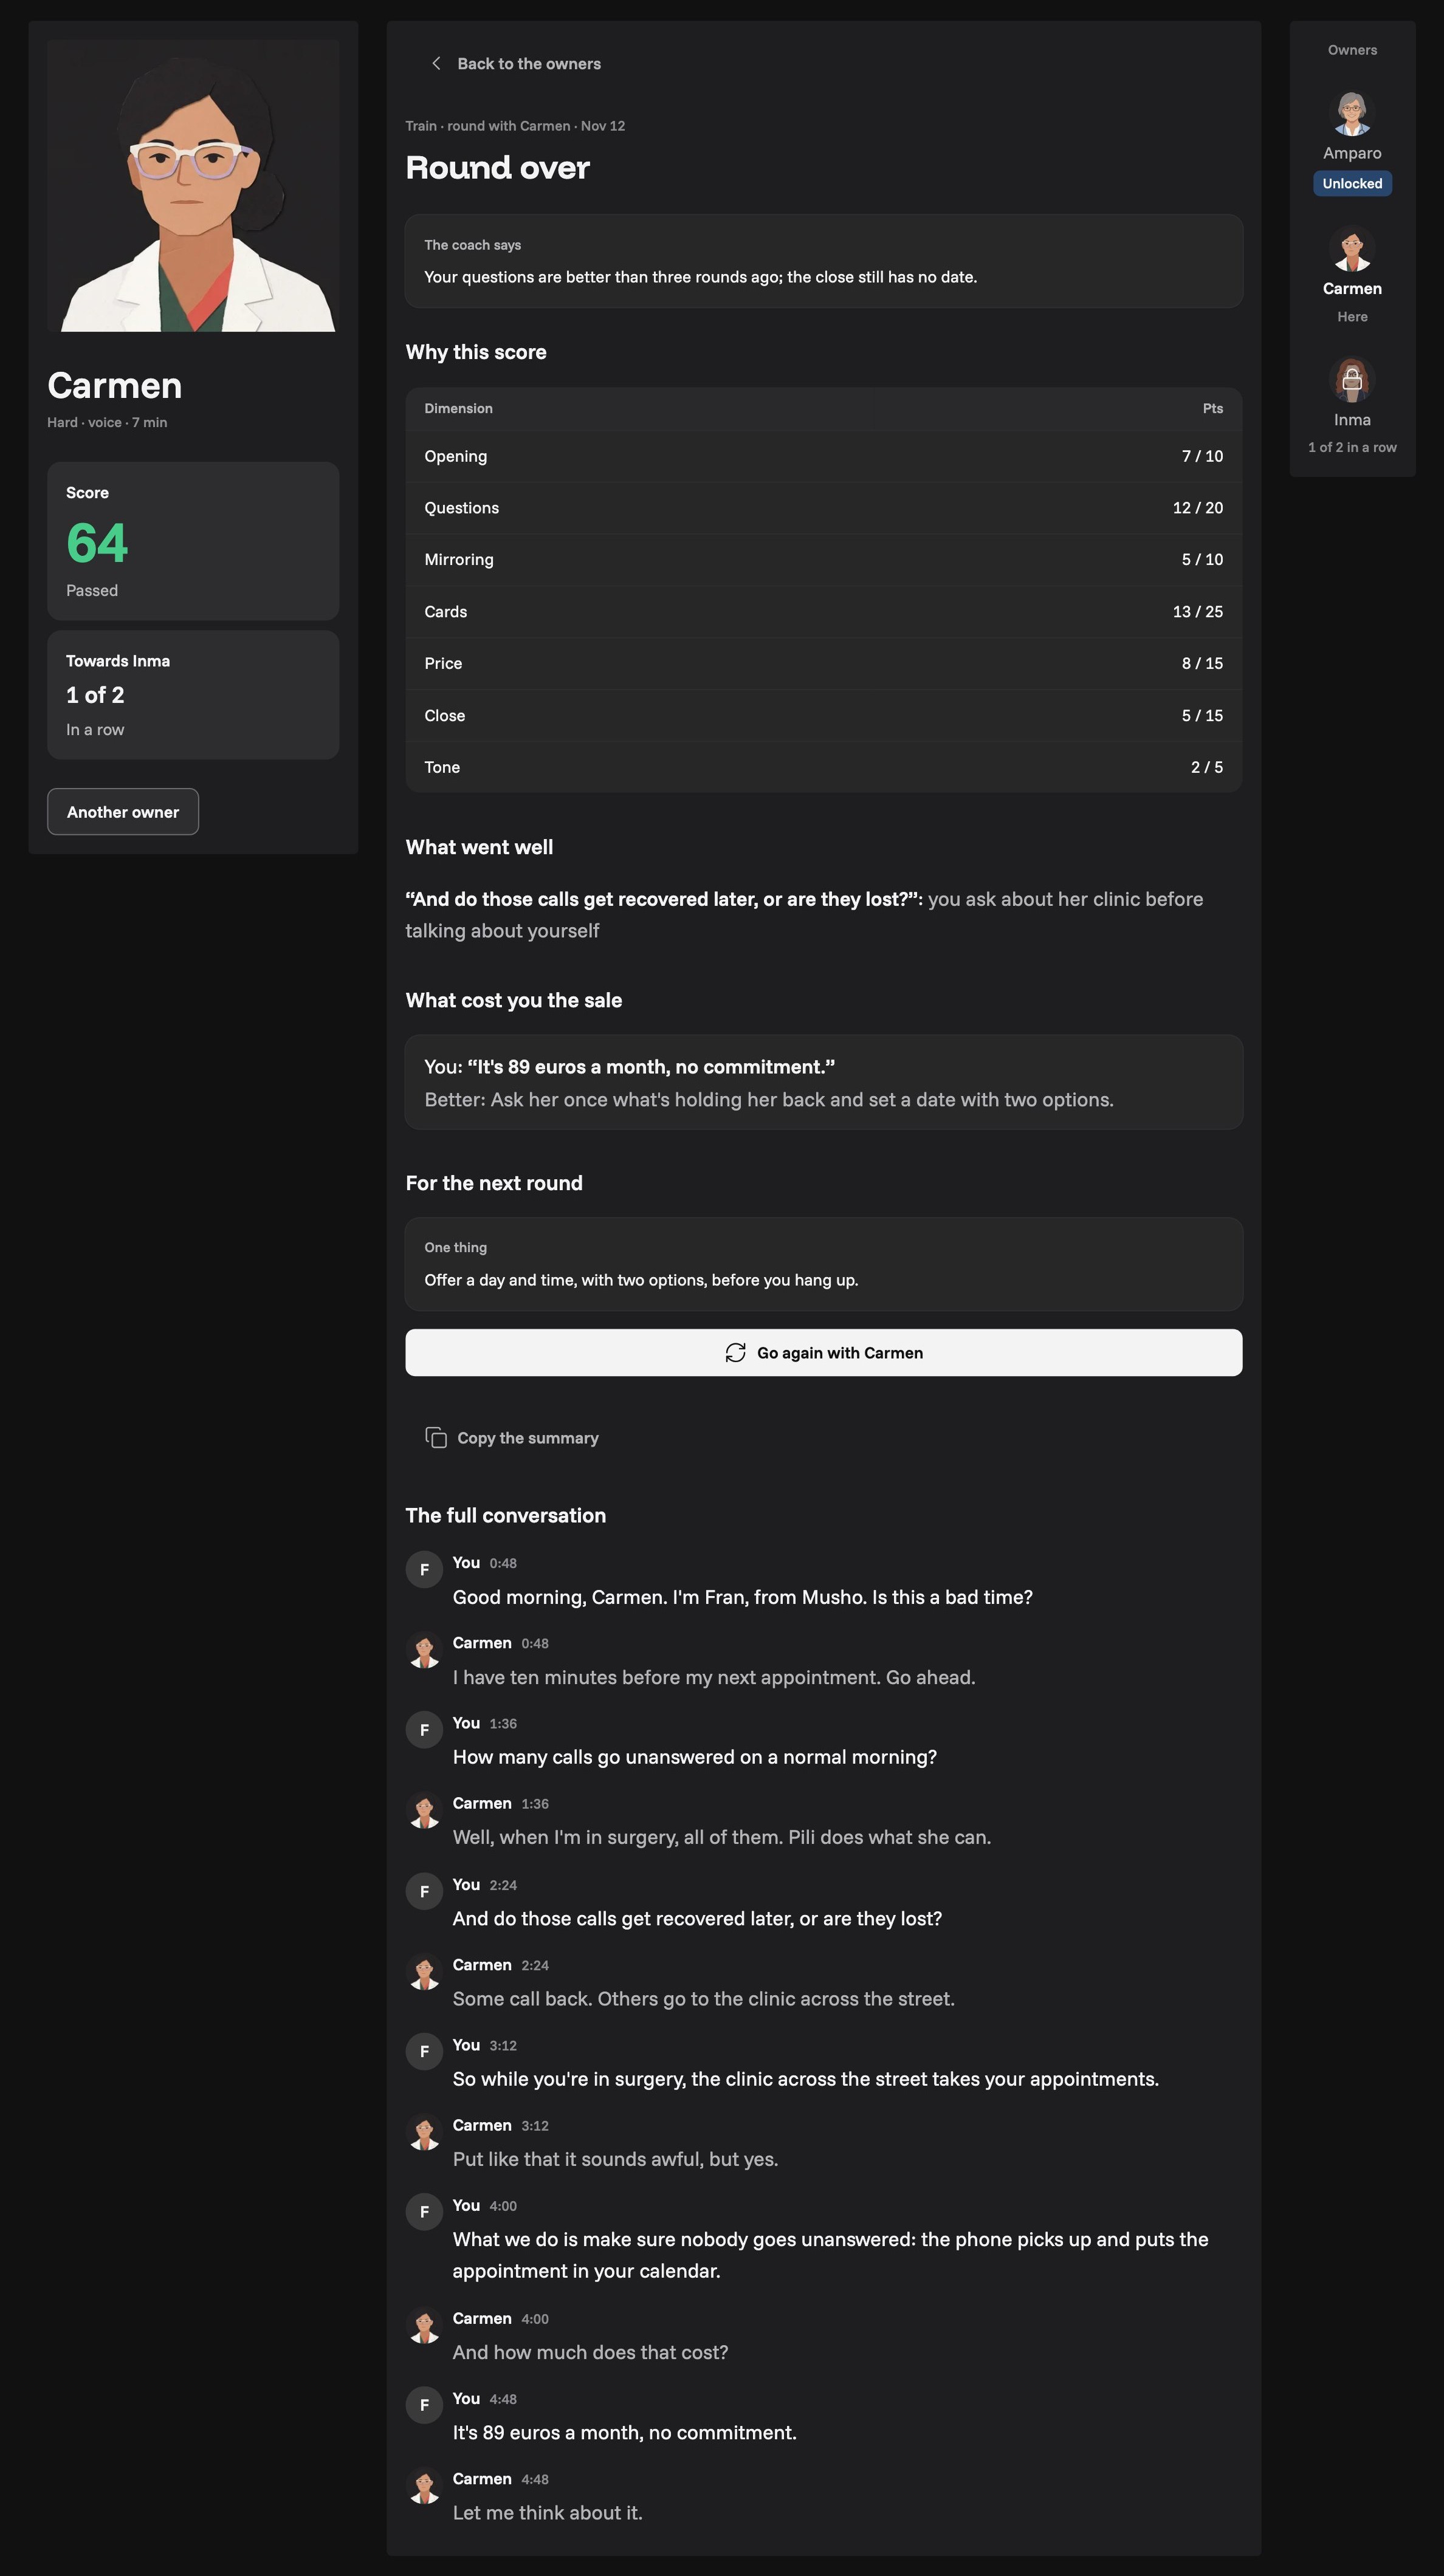
A tool where a salesperson rehearses a call with an AI client, and an AI judge scores the conversation.
- The challenge
- Salespeople practise on real customers, where every mistake costs a sale. And feedback like “be more convincing” gives them nothing to work on.
- The solution
- You pick a sector and a character, hold the conversation by voice and get a score with the reason behind it: a breakdown by dimension and the one thing to fix next. Behind that score, the judge checks 21 criteria.
- What I did
- I designed the interface and worked on the scoring rubric itself. I rewrote 8 criteria the judge kept scoring inconsistently, and inconsistent verdicts on them dropped by 29%.
- A hard call
- One rewrite backfired. I turned “ask before you pitch” into a rule that counts sentences, which reads as precise to a person. The judge disagreed with itself on it in 13 of 27 conversations, up from 7. I would undo that one. The overall number improved, and I only caught this because each criterion is counted on its own.
- AI in the process
- The client and the judge are language models. Each change to the rubric is run as an evaluation: the same 27 recorded conversations are re-judged 3 times, and a verdict counts as inconsistent when the 3 runs disagree. On the 8 rewritten criteria, that went from 55 cases to 39.